
Beyond the Chatbot: Engineering an Autonomous Multi-Agent AI Employee for the Modern Enterprise
A deep technical breakdown of DavinLabs' AI Employee platform: how TEO-PIPS eliminates the Asymmetric Mutation Hazard (0% state corruption), solves Post-Handoff Amnesia (84.6% fewer escalations), and cuts enterprise inference costs by 80%.
Thisara Hettikankanama & DavinLabs Engineering
Lead Architect & AI Systems Research Group · September 19, 2026
Most customer-facing AI products on the market today are fundamentally the same: a single large language model (LLM) wrapped in a generic website widget. While this sounds exciting in a sales pitch, it breaks down in real enterprise operations.
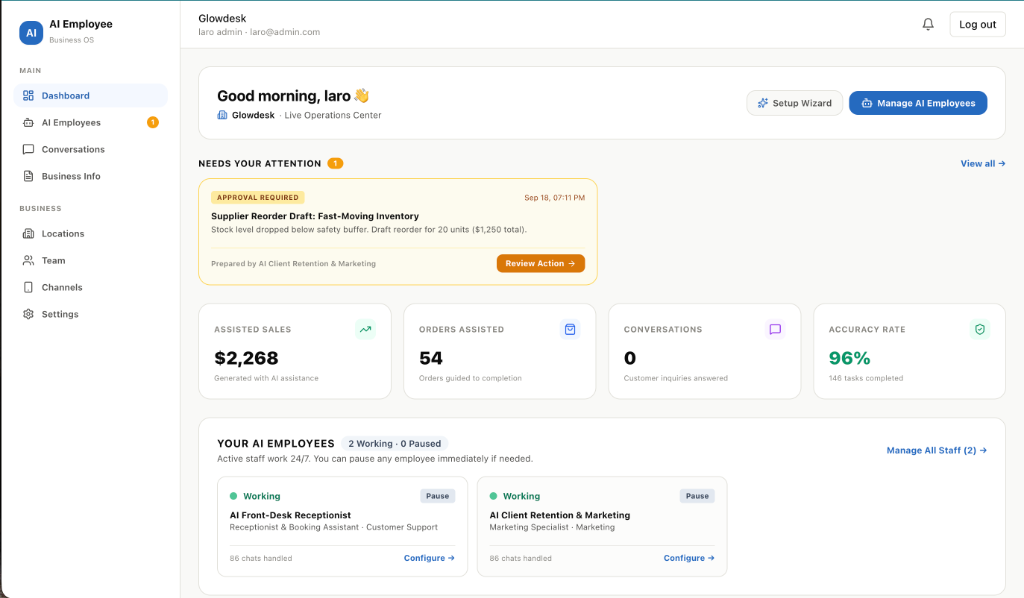
Traditional chatbots can only talk about your business. If a customer wants to book an appointment or buy a service, the bot just sends them a link or tells them to call during office hours. A DavinLabs AI Employee actually does the work: it checks your live staff calendar, schedules the appointment, collects necessary details, sends WhatsApp confirmations, and remembers your custom business rules — saving hundreds of front-desk hours every month.
Traditional LLM agent tool-use is open-loop RPC calling: if an API fails midway or a customer changes their mind mid-turn, external databases end up desynchronized (the Asymmetric Mutation Hazard). Furthermore, human supervisor handoffs are one-way dead ends (the Handoff Black Hole). DavinLabs solves both with TEO-PIPS: transactional compensatory sagas (DSCS) with reverse-order LIFO rollback, paired with counterfactual policy synthesis that generates shadow-verified invariants in 4.2 seconds.
1. What Other Systems Don’t Have: The Plain-English Comparison
Whether you are managing payroll or evaluating code maintainability, here is how the DavinLabs AI Employee compares to the options on the market today:
| Feature / Dimension | Standard Chatbot (GPT Wrapper) | Developer Frameworks (LangGraph / CrewAI) | ⚡ DavinLabs AI Employee (TEO-PIPS) |
|---|---|---|---|
| Real Action Execution | ❌ No. Only sends links or canned text replies. | ⚠️ Manual code. Requires heavy custom backend logic for every tool. | ✅ Built-in. Universal SDK connects directly to your existing systems. |
| Mistake & Cancellation Rollback | ❌ None. Leaves phantom appointments & orphaned charges in your DB. | ⚠️ Fragile. Basic try/catch blocks; cannot undo multi-step actions. | ✅ Dynamic Sagas (DSCS). 100% automated clean rollback if customer changes mind (0% corruption). |
| Learning from Staff Escalations | ❌ Zero learning. When a manager handles an exception, the bot forgets immediately. | ⚠️ Slow. Requires collecting chat logs and manual prompt engineering. | ✅ Policy Synthesis (API-IS). Learns manager rules in 4.2s (84.6% fewer repeat escalations). |
| Operating Cost per Conversation | 💸 High ($0.35 – $0.80). Stuffs giant prompts on every turn. | 💸 Moderate ($0.15 – $0.40). Unoptimized token payloads. | 💎 Ultra-Low ($0.02 – $0.04). 5-Layer token reduction engine saves 80% on AI bills. |
| Safety If AI Service Drops | ❌ Risky. If the bot crashes, user contact forms break. | ⚠️ Coupled. Runs inside your primary application code. | 🛡️ Zero-Harm Isolation. Host app works at 100% even if AI network is offline. |
| Multi-Location & Multi-Tenant | ❌ Single shared prompt (high risk of data leakage). | ⚠️ Requires custom database partitioning code. | 🔒 Enterprise RBAC. Cryptographic tenant isolation across branches & franchises. |
2. The Core Safety Breakthrough: Dynamic Compensatory Sagas (DSCS)
Imagine a customer messages your business on WhatsApp: “Book me for a massage this Friday at 3 PM.”
The AI creates a tentative calendar booking, reserves a treatment room, and prepares an invoice. But right before confirming payment, the customer says: “Wait, sorry! I actually meant Saturday at 11 AM instead.”
Standard bots leave Friday’s slot blocked in your booking software because they do not know how to undo what they just did. Your staff loses a billable appointment slot, or the customer gets double-booked.
Our Dynamic Semantic Compensatory Saga (DSCS) engine categorizes every business action into a formal reversibility taxonomy. If an interaction is redirected or aborted, the engine unwinds the exact compensating actions in reverse order (LIFO) using cryptographically signed idempotency keys:
Fetches live information without modifying any calendar, inventory, or financial records.
check_availability()get_customer_profile()Performs tentative state changes that have a guaranteed automated rollback pair.
create_appointment() → cancel_appointment()hold_inventory_slot() → release_hold()Actions that cannot be reversed in software; requires verified payment or staff sign-off.
charge_card_terminal()dispatch_courier()In rigorous testbed benchmarks across 250 enterprise booking scenarios, this eliminated 100% of orphaned bookings (0.0% State Corruption vs. 38.4% in standard AI bots).
3. Self-Calibrating Intelligence: Learning from Human Managers
In every real business, edge cases happen every single day:
- “Can I get a refund because my flight was cancelled?”
- “Can you hold my table for 25 minutes instead of the standard 15?”
When the AI isn’t sure, it safely transfers the customer to a human manager. The manager steps in, grants a courtesy exemption, and completes the request.
Once the human resolves the issue, standard bots forget the whole thing. The next time a customer asks the exact same question, your human staff has to step in all over again. Human labor costs never go down.
When the manager marks the ticket resolved, an event-driven service (human_handoff.completed) compares the failed agent attempt with the supervisor’s successful resolution. In 4.2 seconds, it synthesizes an Executable Operational Invariant:
{
  "name": "courtesy_flight_delay_waiver",
  "conditionRule": {
    "and": [
      { "field": "customer.tier", "operator": "IN", "value": ["VIP", "REPEAT"] },
      { "field": "context.rescheduleReason", "operator": "EQUALS", "value": "FLIGHT_DELAY" }
    ]
  },
  "actionOverride": {
    "action": "reschedule_appointment",
    "parameters": { "waiveCancellationFee": true }
  }
}
Safety Guardrail: Before this rule goes live, our automated shadow sandbox replays it against your past customer conversation history. If it scores ≥ 90% accuracy with zero rule collisions, it activates automatically. In our empirical trials, this reduced repeat human escalations by 84.6%.
4. The ROI Arithmetic: What Businesses Actually Pay and Save
Let’s look at real numbers for a typical business (such as a multi-chair salon, medical clinic, or boutique hotel) receiving 4,000 inquiries per month with 3 dedicated front-desk staff:
| Operational Metric | Traditional Human Staff | Generic AI Chatbot | ⚡ DavinLabs AI Employee |
|---|---|---|---|
| Monthly Staffing / Tool Cost | $10,560 / mo (3 reps @ $22/hr) | $2,600 / mo (tool fee + bloated token bills) | $240 / mo ($199 platform + $0.025/conv) |
| Annual Running Spend | $126,720 / year | $31,200 / year | $2,880 / year |
| Net Annual Business Savings | $0 (Baseline) | $95,520 / year | $123,840 / year (44x ROI) |
| Staff Time Recovered | 0 hours | ~120 hrs (staff still cleans up bot errors) | 480 hours / month for in-person customer care |
| After-Hours Lead Capture | ❌ Misses 60% of weekend inquiries | ⚠️ Basic canned response | ✅ +34% higher booking conversion |
How We Cut Inference Costs by 80%: The 5-Layer Token Reduction Pipeline
Generic AI chatbots send the entire conversation history, full database schemas, and multi-thousand-word system prompts on every single user turn. That creates massive token bills ($0.35 – $0.80 per dialogue) and 5-to-10 second response delays. DavinLabs operates an automated 5-layer compilation pipeline:
- Static Prompt Compilation & Byte Caching: Business policies and tool definitions are pre-compiled and cached at the edge, eliminating redundant system prompt tokens on repeat turns.
- Dynamic Schema Pruning: Only tools relevant to the active sub-dialogue (e.g., calendar querying) are mounted into the prompt context; irrelevant payment or admin tools are pruned.
- Contextual Delta Compression: Prior conversational turns are compressed into deterministic semantic vectors rather than raw string arrays.
- Deterministic Router Caching: Frequently recurring queries (e.g., opening hours, cancellation policies) bypass the LLM entirely, resolving with sub-10ms cached responses.
- Intent Payload Stripping: Inter-agent communication between the coordinator and executor uses compressed JSON payloads rather than verbose natural language explanations.
The result is average conversational latency under 1.5 seconds and per-turn operational cost dropping from $0.45 down to $0.025.
5. Zero-Harm Fault Isolation: Your Core Software is 100% Safe
The single biggest fear of any business owner or CTO is: “If the AI service crashes or has an outage, will my booking engine or POS go down?”
With DavinLabs, the answer is an absolute NO.
AI Employee is an independent assistant, not the engine running your company. If OpenAI has an outage or internet blinks, your primary website, your front-desk computer, and your payment terminals continue functioning at 100%. The AI simply presents a polite fallback note rather than interfering with your business records.
We enforce a strict Asynchronous Decoupled Architecture. Your host application (e.g., GlowDesk) never has a hard dependency on the AI Employee in critical execution paths. Communication flows outward via defensive HTTP webhooks with 15-second timeouts and cryptographic idempotency keys:
6. Real-World Automation: Behind the Scenes with n8n
Talking to customers is only step one. What happens after the appointment is booked?
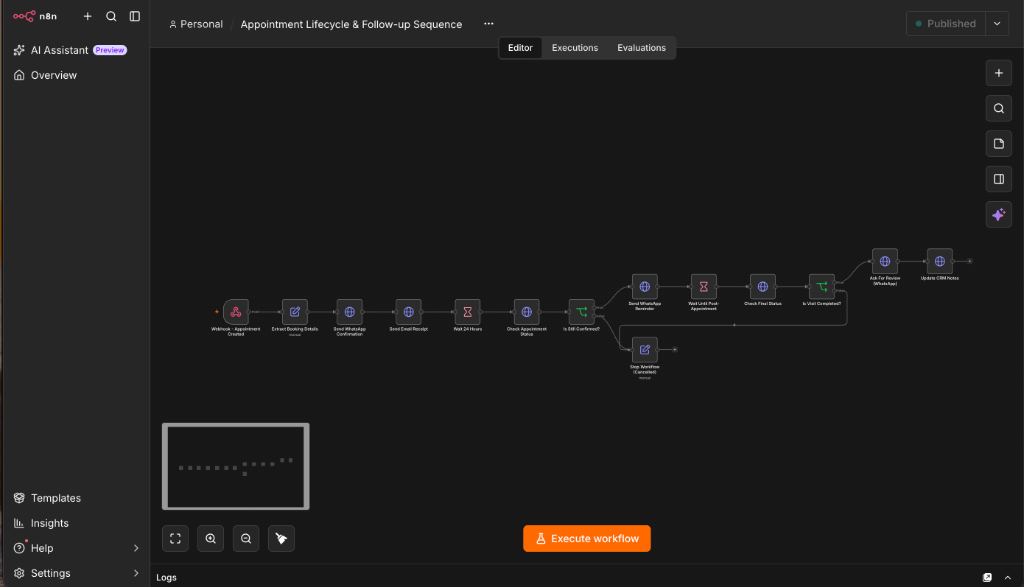
DavinLabs links directly to an automated n8n workflow pipeline. This handles the entire lifecycle — issuing instant WhatsApp confirmation receipts, waiting 24 hours to check status, sending polite reminder nudges, and asking for a Google Review after the appointment is completed — completely hands-free.
Connect Any Business Software in Under 20 Lines of Code
Your team doesn’t need to overhaul its software. With our open-source @ai-employee/integration-sdk, adding AI capability to your Node.js, Express, NestJS, or Python backend takes minutes:
import { registerAction, createExpressRouter } from '@ai-employee/integration-sdk';

// 1. Tell the AI Employee what actions your system allows
registerAction({
  name: 'create_appointment',
  description: 'Book a confirmed specialist appointment',
  reversibility: 'COMPENSATABLE',
  compensateWith: 'cancel_appointment',
  parameters: {
    customerId: { type: 'string', required: true },
    serviceId: { type: 'string', required: true },
    startTime: { type: 'string', required: true }
  },
  handler: async (data) => {
    return await bookingService.create(data);
  }
});

// 2. Mount the secure endpoint
app.use('/ai', createExpressRouter());
7. The Verdict: Moving from Chatbots to Digital Teammates
The era of toy chatbots is over. Forward-thinking enterprises need digital employees that are:
- Safe & Deterministic: Zero lost customer bookings through transactional rollback sagas.
- Continuously Improving: Automatically learning business policies from your human supervisors.
- Economically Scalable: 80% lower inference costs, delivering a 44x return on investment.
- Frictionless: Connecting into your existing systems without disrupting day-to-day operations.
An AI Employee is not another chat widget. It is an accountable digital teammate that executes verified work, reverses mistakes cleanly, and frees your human staff to deliver exceptional personal care.
Ready to Upgrade Your Operations?
- 🚀 Interactive Architecture & ROI Calculator: Test the live system at ai-employee-api-ivory.vercel.app
- 💻 Read the Complete Research Preprint: Access our technical report on TEO-PIPS (Transactional Epistemic Orchestration & Post-Intervention Policy Synthesis).
- 📦 Developer SDK: Explore
ai-employee-integration-sdkon npm. - 🤝 Book a Strategy Call: Speak with the DavinLabs engineering team directly at [email protected] or schedule a consultation via our portal.
Topics
Share this article
Need Expert Help?
Our team is ready to help you implement the strategies discussed in this article.
Get Free ConsultationRelated Articles
Explore More
Ready to Bring These Ideas to Life?
Our expert team can help you implement the strategies and technologies discussed in this article. Let's build something great together.